Hardware can change scientific decisions硬件可能改变 科学决策
Hardware is an overlooked reproducibility variable in AI-driven science: silent numerical faults can change evidence selection and experimental decisions even when aggregate metrics remain unchanged.硬件是 AI 驱动科学中一个被忽视的可重复性变量:静默数值故障可能在汇总指标不变时,改变证据选择和实验决策。
hERGThe shortlist retains the same number of labeled blockers, but which compounds are sent for testing changes. See the testing assignments →候选名单中的标注阻断剂数量不变,送检的化合物却变了。查看检测分配 →
SciFactIn combinations selected for changed retrieval lists, agents can return the same verdict while reading or citing different evidence. See the selection criteria and controls →在按检索列表变化筛选的组合中,Agent 的结论不变,读取或引用的证据却可能改变。查看筛选条件与对照 →
HReference state. Values from a matched healthy execution.参考状态。来自匹配健康运行的数值。
CCandidate state. Values captured at the same computation site on faulty hardware.候选状态。在故障硬件上同一计算位置捕获的数值。
Paired replay on healthy hardware
Case 1 (size-dependent) faults appear more often on tested large-matrix paths than on short probes. Case 2 (expanded-trigger) faults also appear on short probes.Case 1(尺寸依赖型)在所测试的大矩阵路径上比短探针更常出现异常;Case 2(触发范围扩展型)也会在短探针上出现异常。
6/8
Of eight Case 2 sources, six changed the hERG shortlist and six changed testing assignments八个 Case 2 来源中,六个改变了 hERG 候选名单,六个改变了检测分配
2
labeled hERG blockers, K12252 and K1461, assigned to advancement without testing in faulty runs标注为 hERG 阻断剂的 K12252 和 K1461,在故障运行中被安排不经检测直接推进
39/39
changed decisions recovered by restoring the agent’s pre-read execution state; replacing the prediction file recovered none恢复 Agent 读取前的执行状态后,39 个被改变的决策全部复原;仅替换预测文件未能恢复
42.4%
less time for forward execution plus verification than the original FP64 checks, with identical flags and recovery outputs前向计算与验证总耗时降幅,比较基准为原始 FP64 校验;异常标记与恢复输出保持一致
Abstract摘要
AI 驱动科学的可重复性,还取决于运行计算工具的硬件。汇总指标稳定,不能保证证据选择和 Agent 决策也稳定。
Reproducibility in AI-driven science also depends on the hardware that produces tool values. Stable aggregate metrics do not guarantee that evidence selection or agent decisions will remain stable.
In production training clusters, we found two patterns of silent numerical faults on GPUs: programs reported no errors and training continued, while the underlying calculations had quietly diverged. Lei et al. (OSDI’26) detected 18 silent data corruption (SDC) incidents involving 13 faulty GPUs during a production deployment spanning 35 million GPU-hours. In another OSDI’26 study of 23 GPUs affected by SDC, standard synthetic microbenchmarks missed over 60% of the defective devices, and conventional ECC and thermal protections did not capture the observed logic-level faults. Passing a general device test therefore does not establish correctness for a specific scientific computation.
We replay captured tool values in paired runs on healthy hardware. In hERG screening with the native Biomni A1 agent (GPT-6.1 Sol), the shortlist retains the same number of labeled blockers while shortlist membership and testing assignments change, including two labeled blockers advanced without testing, although the reference decision was to test them. In SciFact combinations selected for changed retrieval lists, verdicts can stay unchanged while evidence paths change; the unfiltered cohort shows no excess over healthy-repeat variation. Both experiments motivate checking the evidence and objects behind scientific decisions alongside aggregate results.
To address this, we propose BioAgent-DF, an end-to-end scientific decision-fidelity framework spanning GPU numerical verification, trusted recomputation, agent state restoration and decision certification. We extended our experiments from hERG drug safety screening to GB1 protein engineering and superconducting materials screening and observed that numerical faults changed agent decisions in all three tasks. After recovery with BioAgent-DF, agent decisions in all three tasks matched the reference decisions from matched healthy runs. Compared with the original FP64 verification, streaming verification reduces the added verification time by 78.2% and the total compute-and-verification time by 42.4%.
From silent numerical faults in production clusters to decision fidelity in research agents, we aim to make BioAgent-DF a trusted decision core that extends these safeguards to physical experiments. For future fully automated wet labs, this infrastructure would span computation, decisions, execution and observation.
Every scientific decision, verifiable against evidence.Every experimental step, traceable.Every conclusion, open to re-examination and correction from the original evidence.
Outlook展望
BioAgent-DF for Next-Generation LabsBioAgent-DF:面向下一代实验室
Towards Trustworthy and Controllable Fully Automated Wet Labs
Next-generation fully automated wet labs must design and run experiments, assess which computational results are trustworthy, and determine which decisions may be submitted and which states can be restored after an error. We validated the computational and decision steps in hERG testing assignment. Linear-layer checksums flagged every tested fault source, while routine checks raised no alerts. After the agent had used faulty values, replacing the file did not correct its decisions; restoring the execution state did. All submitted decisions matched the certificate.
We aim to apply BioAgent-DF to robots and instruments. The agent can reason ahead while instruments act only after a decision is verified. After an error, digital state can be rebuilt while retaining records of completed operations and measurements.
Solid: validated in this work (appendix cited)实线框:本文已验证(附录可查)
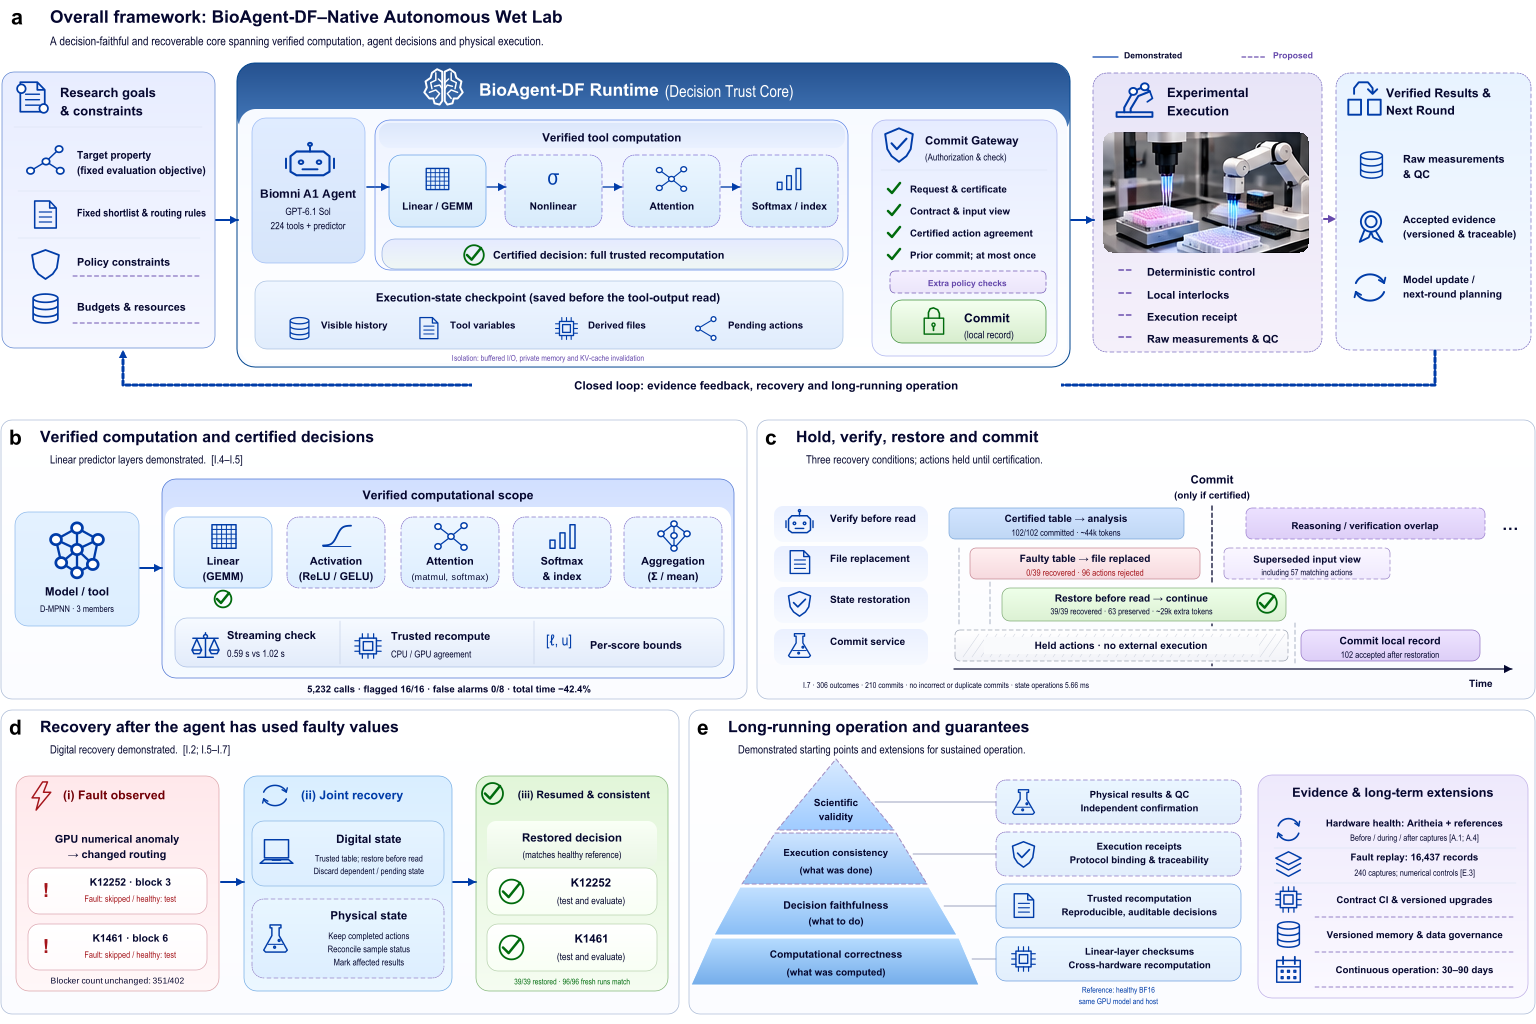
aOverall framework: a validated decision-fidelity core and a proposed closed loop总体架构:已验证的决策保真核心与拟议的闭环
Panel a traces the closed loop from research goals to experimental feedback, with the decision-fidelity core in the middle validated in this work.
图 a 展示从研究目标到实验反馈的闭环,中间的决策保真核心已在本文验证。
Validated in this work本文已验证
The native Biomni A1 agent runs GPT-6.1 Sol, with 224 standard tools and one hERG prediction tool. The decision rules are fixed before capture: select a shortlist of 402 compounds and assign hERG testing by a threshold. The prediction tool’s linear layers are checked with streaming checksums during the forward pass; flagged predictions are recomputed on trusted hardware, and certificates are issued by full trusted recomputation. Before the agent reads tool output, its execution state is saved: visible history, tool variables, derived files and pending decisions. The commit service checks the request, the certificate, the computational and decision settings, the input version, whether the decision agrees with the certified decision, and whether the request was already committed. Each request is committed at most once, and a commit is a local record.
Checks for nonlinear operators, attention and softmax; buffered I/O and messages, private memory and KV-cache invalidation; checks for dependency closure, sample and protocol binding, device state and safety policy; robot and instrument execution, QC and execution receipts; and experimental results feeding back to update the model.
The validated part answers what a decision was based on and whether it matches the decision under healthy hardware. The proposed part answers what actually happened at the bench.
bTrusted computation: linear layers validated, other operators proposed可信计算:线性层已验证,其余算子为拟议
Validated in this work本文已验证
Row and column checksums with a rounding-error bound check linear computations of the form . After deduplication there are 5,232 linear calculations: all 16 fault sources were flagged, eight healthy verifier runs raised no false alarm, and none of the 16 reference and restoration passes was flagged. By contrast, integrity checks on stored data and checks that probabilities are finite and between 0 and 1 flagged none of the 16 fault sources. An independent CPU implementation agreed on all calculations, and trusted recomputation on a healthy data-center GPU reproduced the reference bit for bit.
On the matched data-center GPU workload, streaming verification reduced the time for forward execution and verification from 1.02 s with the original FP64 checks to 0.59 s. The native forward pass took 0.47 s, and double execution took 0.88 s. Streaming verification reduced the added verification time by 78.2% and the total time by 42.4%, with 25.8% overhead over the native forward pass. Flags and recovery outputs were identical to the original implementation.
R1+M recovers decisions: R1 recomputes flagged predictions and M also recomputes the 68 compounds within ε of a decision boundary, after which the shortlist and testing assignments match the healthy reference in all 16 sources; the same number of compounds chosen at random or by ensemble disagreement left discrepancies. Full trusted recomputation provides certification: it issued every certificate in the single-request experiments.
Extend verification to activations, attention, softmax, indexing and aggregation. We find that upstream numerical deviations can propagate through subsequent operators and change attention positions or model choices: all 2,048 rows of attention probabilities are finite and normalized, yet 58 change their maximum-attention position; under Case 1, finite LLM option scores still change the selected option. Certify decisions using a valid error bound for each score.
This work shows that finite values, error-free execution and unchanged metrics are not grounds for trust, and it gives a verification path that holds for linear layers. Extending coverage to other operators is the next step.
Each of the 102 requests (16 fault sources plus one healthy reference, two tasks and three repeats) was evaluated under three recovery conditions. Verification before the agent read the table cost about 44,000 tokens per request. After the read, file replacement retained the previous execution state, and the commit service rejected all 96 decisions based on superseded faulty inputs, including 57 whose content matched the reference. Restoring the pre-read execution state allowed every request to submit the reference decision, at about 29,000 additional tokens and 5.66 ms of state operations per request. Across the three conditions, 306 outcomes included 210 commits, all consistent with the certificate and none duplicated. Section 01 compares recovery of the changed decisions.
Speculative execution overlaps the agent’s reasoning with verification in time to cut waiting latency. Isolation rules keep uncertified information out of the official database, shared memory and device interfaces, and away from other agents.
What this shows: replacing the file cannot recover the decision; the execution state must be rolled back, and every commit must check the input version. Speculation and isolation are designs built on top of this, and whether they pay off depends on the fault rate and the length of the experimental cycle.
dRecovery after the read: digital side validated, physical side proposed读取后的恢复:数字侧已验证,物理侧为拟议
Validated in this work本文已验证
In Case 2 fault sources, K12252 and K1461, both labeled hERG blockers, were assigned to advancement without hERG testing in block 3 and block 6 respectively; the healthy decision is to test them. The shortlist still held 351 blockers among its 402 compounds.
Decision recovery with R1+M
checksum flag
R1 recomputes flagged predictions
M recomputes 68 near-boundary compounds
All 96 fresh trajectories on R1+M inputs reproduced the healthy decisions.
Certification and state restoration
full trusted recomputation issues the certificate
restore the execution state from before the read
discard dependent state and pending decisions
continue with the certified table
Tool state and agent execution state were restored together; submitted decisions matched the certificate.
Keep completed physical operations, reconcile sample status and mark affected results.
保留已完成的物理操作、核对样本状态、标记受影响结果。
Why it matters意义
What this work demonstrates is joint recovery on the digital side: the tool state and the agent’s execution state are restored together. How to preserve irreversible physical facts is a new problem that sets fully automated wet labs apart from purely software systems.
The Aritheia arithmetic-probe tool is public: on the faulty GPU, 15 of 69 checks detected an anomaly, and none did on two healthy GPUs. Healthy references were measured before, during and after every capture round. The residual bank keeps 16,437 residual records from 240 captures for replay. Ordinary precision differences serve as controls: on healthy hardware, differences in the precision used for intermediate summation in BF16 matrix multiplication can change Top-10 nearest-neighbor membership in the PBMC single-cell dataset; zero-residual controls leave endpoints unchanged; and differences between healthy repeats are measured separately as the comparison baseline.
Hardware drift monitoring and isolation; regression tests covering drivers, compute libraries, models and prompts; isolation, merging and revocation of memory; a digital twin; and 30 to 90 days of continuous operation.
Long-term reliability has to be maintained continuously. This work provides three starting points: probes, reference measurements and replay data.
长期可靠性需要被持续维护。本文提供了探针、参考测量和回放数据三个起点。
01From tool state to scientific decisions从工具状态到科学决策
Silent numerical faults change which compounds get tested静默数值故障改变了哪些化合物会被送检
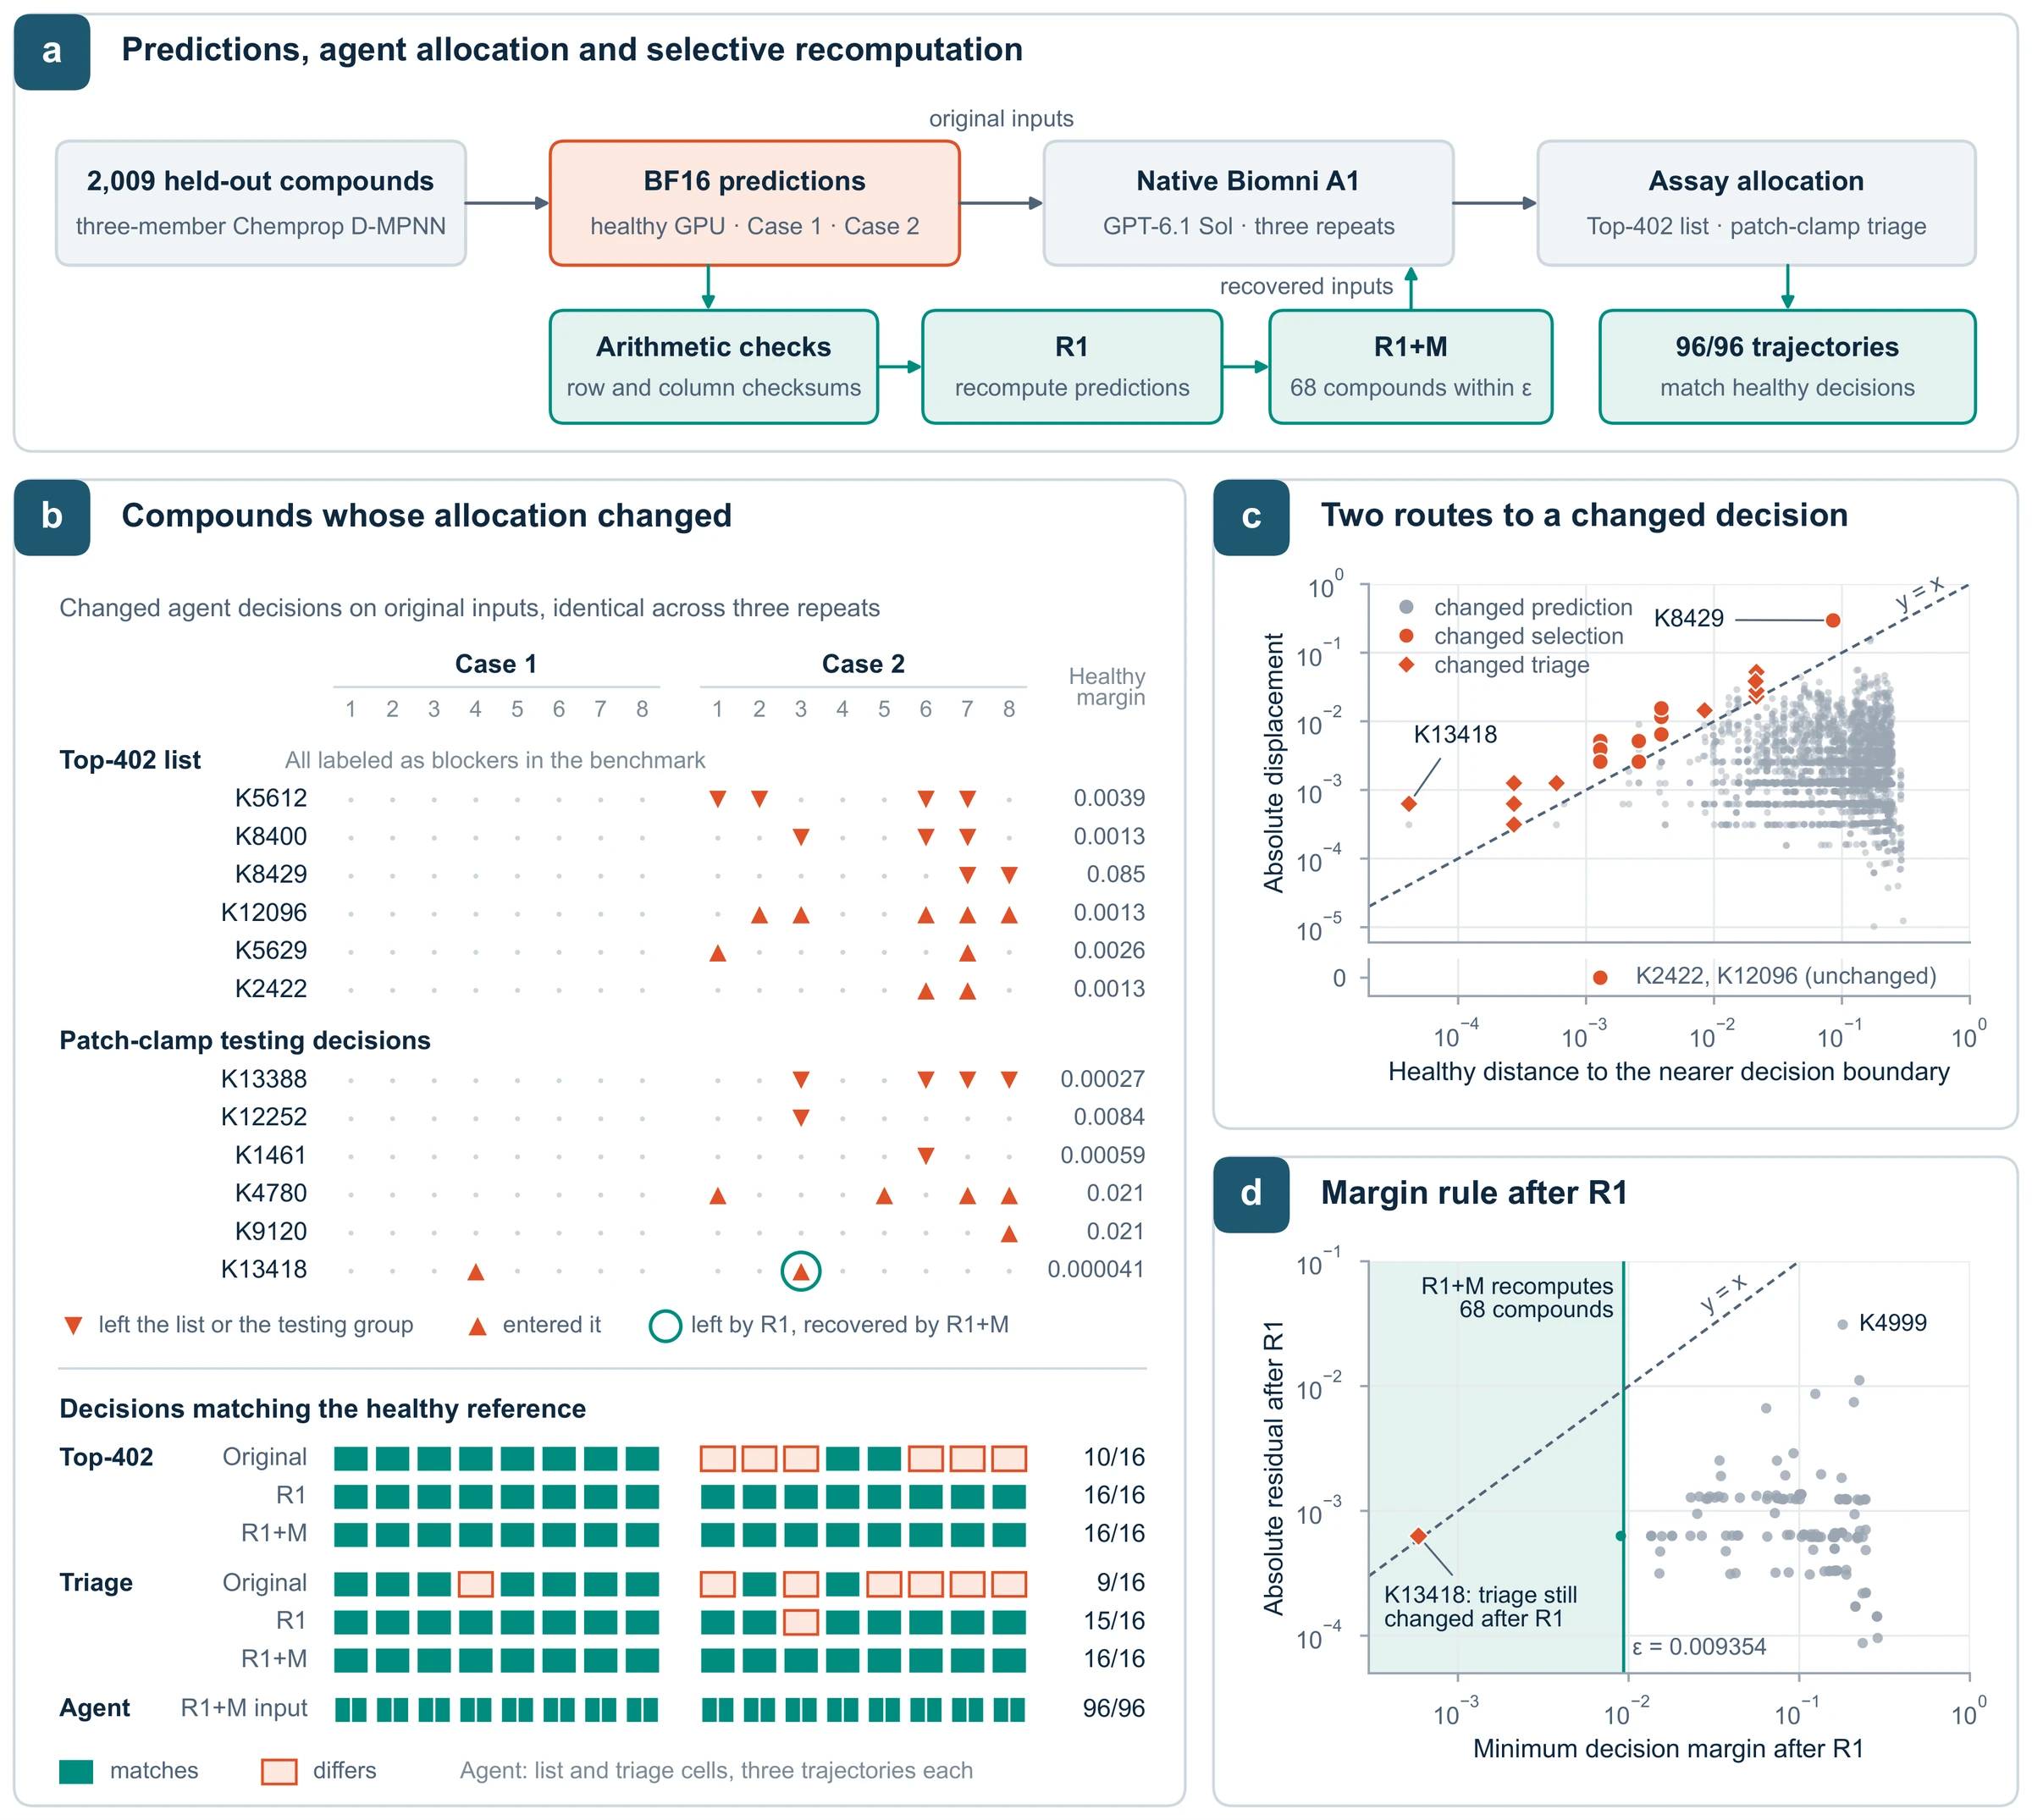
A three-member Chemprop D-MPNN ensemble predicts blockade of the hERG potassium channel, a cardiac-safety liability, for 2,009 held-out compounds. A native Biomni A1 agent (GPT-6.1 Sol) selects the 402 highest-scoring compounds for measurement and assigns every compound to patch-clamp testing or advancement without testing. Sixteen saved BF16 passes, eight per fault pattern, are compared with a healthy reference from the same GPU model and host.
Case 1 preserved shortlist membership; only one of eight sources changed testing assignments. Of eight Case 2 sources, six changed shortlist membership and six changed testing assignments.
Every list replacement exchanged labeled blockers. The shortlist therefore still contained 351 labeled blockers among 402 compounds, even though its members and testing assignments changed. K12252 and K1461, both labeled blockers, were assigned to advancement without testing although the reference decision required testing. The changes extended beyond near-ties: K8429 fell from 0.880 to 0.584 and left the list, while K12096 and K2422 entered with unchanged predictions because competitors fell.
R1 recomputes on healthy hardware the predictions flagged by row and column checksums with a rounding bound. R1+M also recomputes the 68 compounds whose decision margin falls below . Selection and testing assignment then matched the healthy reference in all 16 sources, and all 96 fresh Biomni trajectories on R1+M inputs reproduced the healthy decisions.
Enlarge放大Figure 2. Changed hERG testing assignments and recovery. (a) BF16 predictions feed native Biomni selection and testing assignment; R1 recomputes predictions flagged by arithmetic checks, and R1+M adds a margin rule that also recomputes 68 compounds near decision boundaries. (b) Changed decisions across 16 sources; the ring marks the discrepancy left by R1 and recovered by R1+M. Healthy margin is distance to the affected decision’s boundary; lower rows show recovery and the decisions of native Biomni runs on R1+M inputs. (c) Prediction displacement versus healthy distance to the nearer boundary; highlights mark changed decisions, and the lower strip shows entry with unchanged predictions. (d) R1 residual versus the minimum decision margin computed from R1 scores; shading marks R1+M selection. Dashed lines in (c,d) mark equality.图 2|hERG 检测分配的变化与恢复。(a)BF16 预测进入原生 Biomni 的选择与检测分配任务;R1 重算被算术检查标记的预测,M 追加重算 68 个近边界化合物。(b)16 个故障来源中的决策变化;圆圈标出 R1 留下、由 R1+M 恢复的差异。健康余量是参考分数到相关决策边界的距离,下方给出恢复结果与使用 R1+M 输入的 Biomni 决策。(c)预测位移与到较近边界的健康距离;高亮标出决策变化,下方条带显示自身分数不变却进入名单的对象。(d)R1 残差与 R1 分数的最小决策余量;阴影表示 M 的重算范围。(c、d)的虚线表示相等。
Mathematical Foundations of Decision Fidelity决策保真的数学基础
Definition定义
Under the same computational settings and decision rule, scientific decision fidelity means that the final selection or testing assignment matches the decision obtained from trusted reference scores. Evidence reads and citations are compared separately with a reference execution.在相同的计算设置和决策规则下,如果系统最终给出的候选名单或检测分配,与可信参考计算得到的结果一致,我们就称其具有“科学决策保真性”。至于读了哪些文档、引用了哪些句子,则另行与参考运行记录比较。
a
the final decision最终决策
p⋆
the reference scores参考分数
g
the decision rule, specified in advance预先规定的决策规则
Open any step for its explanation, equations and examples.点击下面的步骤,可展开说明、公式和实验例子。
01Check outputs against their inputs用输入核验输出Compare output checksums with input-derived values and the allowed rounding error.先比较行列校验和与预期结果,判断偏差是否超出了允许的舍入误差。
For a linear layer, X has u rows and k inputs, W has v rows and k inputs, and b is a v-entry bias vector. The vector 1 contains ones; its subscript specifies its length.以线性层为例,输入 X 包含 u 行、k 个特征,权重 W 包含 v 行、k 个特征,b 是长度为 v 的偏置向量。公式中的 1 表示各项均为 1 的向量,下标表示向量长度。
The expected row sums χrow and column sums χcol can be computed from X, W and b without forming the full reference product:根据输入 X、权重 W 和偏置 b,可以直接算出预期的行和 χrow 与列和 χcol,无需先重算整张输出矩阵:
Let Ŷ be the observed output. Compare its sums with χrow and χcol. For example, row i is flagged when the magnitude of its computed residual exceeds βᵣ,ᵢ:再将实际输出 Ŷ 的行和、列和与上述结果比较。例如,当第 i 行的校验残差超过允许的舍入误差界 βᵣ,ᵢ 时,就标记这一行:
The residual compares Ŷ1 with χrow. The bound β includes rounding in the declared layer computation and in the checksum calculation; column checks use the corresponding column bounds.这里的残差来自 Ŷ1 与 χrow 的差。误差界 β 同时考虑线性层计算和校验计算中的舍入误差;列检查采用同样的原则。
Why a checksum does not bound each score为什么校验和不能给出每个分数的误差界
For any nonzero η, this error matrix has zero row and column sums. Cancellation can therefore hide individual errors; decision certification requires additional valid score bounds or trusted recomputation.只要 η 不为零,矩阵中就存在误差,但各行、各列求和后仍然为零。这说明正负误差可能相互抵消,掩盖具体数值的偏差。因此,要认证最终决策,还需要有效的逐分数误差界或可信重算。
Streaming verification with conservative fallback带保守回退的流式校验
Our streaming checker shares signed and absolute FP64 tile reductions across row and column checks. A conservative arithmetic guard resolves checks when the original verifier’s decision is unambiguous and falls back to that verifier otherwise. Across the 16 evaluated fault sources, it preserved flags, localization and bitwise recovery outputs while reducing total forward-and-verification time by 42.4% relative to our original FP64 implementation.流式校验在行、列检查之间共享带符号与绝对值的 FP64 分块归约。当保守误差界足以确定原始校验器的判定时,直接给出结果;否则回退到原始校验器。在评价的 16 个故障来源中,标记、定位及逐位恢复输出均与原实现一致,前向计算与验证的总耗时比原始 FP64 实现降低 42.4%。
Mathematical form of the guard判定逻辑的数学表述
For one row or column check, let r64 be the original FP64 residual and β64 its rounding-error bound. The signed margin z64 determines its flag f64: one when z64 > 0, zero otherwise. Let z̃ be the streaming estimate and κ a valid bound on its discrepancy from z64, including rounding in both the residual and bound calculations.对一次行或列检查,r64 是原始 FP64 校验残差,β64 是对应的舍入误差界。残差绝对值与误差界之差 z64 决定标记 f64:大于零时取 1,否则取 0。z̃ 是流式估计,κ 是它与 z64 之差的有效上界,包含残差与误差界计算中的舍入影响。
If the interval lies entirely above zero, flag the check; if it lies entirely below zero, pass it. An interval containing or touching zero triggers the original FP64 check. Under the stated bound, the streaming flag equals the original FP64 flag.区间完全高于零时标记,完全低于零时通过;包含或触及零时调用原始 FP64 检查。在上述误差界成立时,流式判定与原始校验器一致。
02Locate and test the differences定位并检验差异Restore and transplant values at the same coordinates to test which differences affect the decision.在同一位置恢复和移植数值,观察决策是否随之改变,检验哪些差异真正起作用。
Pair a healthy reference state h with a candidate state c captured at the same computation site. For a coordinate or block set S, restoration corrects the candidate; transplantation introduces the captured differences into the reference.在同一个计算位置,分别保存健康参考状态 h 和候选状态 c。对坐标或块集合 S,恢复操作将对应数值换回参考值;移植操作则将候选值放入参考状态。
Here i indexes a tensor entry. When blocks are selected, S denotes the union of their entry coordinates. RS is the restored state and TS the transplanted state.i 表示张量条目的坐标;按块选择时,S 表示这些块包含的全部条目坐标。RS 是恢复后的状态,TS 是移植后的状态。
Continue with the same downstream computation F and compare endpoint D. Restoration tests recovery of D(F(h)); transplantation tests reproduction of D(F(c)). The two directions provide controls for one another. Empty and full edits, healthy repeats and fixed continuation conditions distinguish the intervention from reconstruction errors.继续相同的后续计算 F,比较终点 D。恢复实验检验是否恢复 D(F(h)),移植实验检验是否重现 D(F(c));两个方向的干预互为对照。通过不替换数值、完整替换和健康重复等对照,并保持后续计算条件一致,可以区分干预效果与状态重建带来的误差。
03Recompute selected objects选择性重算Use arithmetic evidence and distance from selection or testing boundaries to choose further recomputation.结合异常位置,以及分数距入选线或检测阈值的距离,选择需要进一步重算的预测。
For fixed threshold and Top-K rules, let d(q) be the L∞ distance to the decision boundary. A rule output can change only if the score displacement reaches that boundary.对于固定阈值或 Top-K 选择,分数变了并不意味着名单一定会变。只有分数位移达到决策边界,规则输出才可能改变。下面用 d(q) 表示分数向量到边界的 L∞ 距离。
q is a score vector and s the currently observed vector. Bg denotes the decision boundary, where g is not locally constant. The L∞ norm is the largest absolute coordinate difference, and dist∞ is distance measured with that norm.q 表示一个分数向量,s 是当前观察到的分数向量。Bg 表示规则 g 不再局部恒定的决策边界。L∞ 范数是各坐标绝对差的最大值,dist∞ 是按该范数计算的距离。
For Top-K membership with a strict cut-off gap, d(q) = (q(K) − q(K+1))/2. An unchanged score can enter or leave when competitors move. M uses current, per-object margins to allocate additional recomputation.对于按分数选取前 K 个对象的规则,如果入选线处没有平局,则 d(q) = (q(K) − q(K+1))/2。即使某个对象自身的分数没有变化,竞争对象的分数变化也可能使它进入或退出名单。M 就是根据各对象当前距离决策边界的远近,安排进一步重算。
For the vector of threshold decisions gi(q) = 1[qi ≥ τ], the boundary distance is d(q) = mini|qi − τ|.对全部对象的阈值决策 gi(q) = 1[qi ≥ τ],边界距离为 d(q) = mini|qi − τ|。
K is the number selected; q(K) is the K-th largest score. In the threshold rule, τ is the specified threshold, i indexes an object, and 1[·] equals one when the condition holds and zero otherwise. R1 recomputes predictions identified by arithmetic checks; M adds objects whose current decision margin is below the empirical threshold ε, determined before evaluation.K 是入选数量,q(K) 是第 K 大的分数。在阈值规则中,τ 是规定阈值,i 是对象索引;1[·] 在条件成立时取 1,否则取 0。R1 重算由算术检查定位到的预测;M 追加重算当前决策余量小于经验阈值 ε 的对象,ε 在评价前确定。
From distance to an interval certificate从边界距离到区间认证
Suppose each score has a valid bound |si − p⋆i| ≤ ei. The admissible set lies within radius max ei of s. A radius smaller than d(s) cannot reach a boundary, so the rule is constant throughout the set.若每个分数具有有效误差界 |si − p⋆i| ≤ ei,可容许集合位于以 s 为中心、max ei 为半径的球内。半径小于 d(s) 时无法触及边界,规则在整个集合内为常值。
The non-negative ei bounds the error of score i. The admissible set is 𝒰 = {q : |qi − si| ≤ ei for every i}. Thus g(𝒰) is the set of decisions obtained from all score vectors allowed by these bounds.非负的 ei 是第 i 个分数的误差上界。可容许集合为 𝒰 = {q:对每个 i,都有 |qi − si| ≤ ei}。g(𝒰) 则是这些误差界允许的所有分数向量对应的决策集合。
Full recomputation gives a singleton set; the specified tie rule then determines its decision, including at a tie.全量重算得到单点集合,规定的平局规则可以确定其决策,包括参考分数恰好平局的情况。
The displacement condition is necessary for a decision change; the interval condition is sufficient, not necessary, for certification.位移条件是决策变化的必要条件,区间条件是认证的充分而非必要条件。
A numerical example: K13418一个具体例子:K13418
Drawn to scale. The shaded band is the range M recomputes, within ε = 0.009354 of τ; it extends beyond both ends of this view.按比例绘制。阴影为 M 的重算范围,即距 τ 不到 ε = 0.009354 的分数,两端均超出图示范围。
In Case 2, block 3, the healthy score was about 0.304710, below the testing threshold τ ≈ 0.30475175. After R1, the score was still about 0.305339, above the threshold, which added a testing assignment.以 Case 2 的第 3 区组为例,K13418 的健康分数约为 0.304710,低于检测阈值 τ ≈ 0.30475175。R1 之后,它的分数仍约为 0.305339,高于阈值,因此比参考决策多安排了一项检测。
The positive residual, about 0.000629, crosses the healthy margin of about 0.000041. M uses only the current distance to the threshold, about 0.00059: it is smaller than ε = 0.009354, so this object is recomputed and the reference decision is recovered.约 0.000629 的向上偏移,已经越过了健康分数距阈值约 0.000041 的间隔。M 无需读取健康参考,只需检查当前分数距阈值约 0.00059,小于预定的 ε = 0.009354,就会将该对象纳入重算。重算后,检测分配恢复为参考决策。
K13418 is labeled a non-blocker in the benchmark; the changed decision adds an unnecessary test.K13418 在基准数据中标注为非阻断剂,这里多出的是一次不必要的检测。
Decision recovery versus full-state recovery决策恢复与完整状态恢复的成本
Recovery cost恢复成本
Recover the decision before the full state决策可以先于完整状态恢复
Let C(S) measure the cost of an admissible edit. The decision endpoint may be membership, order or testing assignment. The two recovery targets have different feasible sets:令 C(S) 表示允许编辑的成本。决策终点可以是名单成员、排序或检测分配。两种恢复成本具有不同的可行集合:
ℛ is the family of allowed coordinate sets S. F continues computation from the saved state; D extracts the endpoint being compared. ρD is the minimum cost of recovering that endpoint, and ρstate the minimum cost of reproducing the full reference state h. C(S) uses the same specified unit in both problems, such as replaced blocks or measured computation time; an infeasible minimum is +∞.ℛ 是允许选择的坐标集合 S 的全体。F 从保存状态继续计算,D 提取要比较的终点。ρD 是恢复该终点的最小成本,ρstate 是恢复完整参考状态 h 的最小成本。两者的 C(S) 使用同一规定单位,例如替换块数或实测计算时间;无可行方案时,最小值记为 +∞。
With the same admissible edits, cost function and fixed deterministic continuation, full-state recovery is sufficient for endpoint recovery. This inclusion establishes the inequality.在相同允许编辑、成本函数和固定确定性后续计算下,完整状态恢复足以恢复终点,因此得到这个不等式。
04Restore the execution state恢复执行状态If incorrect values have already been used, return to the pre-read state and continue with trusted results.如果 Agent 已经读过错误结果,就回到读取之前保存的状态,再使用可信结果继续分析。
The agent’s decision is a = π(H). Here π is its decision procedure, and H includes the visible history, tool-derived variables and prepared decisions. Let H₀ be the saved state before reading a score table. Φ(H, p) denotes continuation from execution state H with score table p available to the tools.Agent 不只依赖眼前的文件,还会使用此前读到的信息和已经生成的变量、名单。我们用 H 表示这些执行状态,用 π 表示 Agent 据此作出决策的过程,即 a = π(H)。H₀ 是读取分数表前保存的状态。Φ(H, p) 表示从执行状态 H 继续分析,此时工具可读取的分数表为 p。
The vector pᶜ is the faulty score table; p⋆ is its trusted reference. File replacement makes the trusted table available, but the agent continues from Hc, the execution state formed using the faulty table:pᶜ 是故障分数表,p⋆ 是可信参考表。只替换文件后,工具可读取的表格已换成可信参考,但 Agent 仍从使用故障表后形成的执行状态 Hc 继续分析:
Execution-state restoration returns to H₀ and continues with the reference table:恢复执行状态则先返回读取前的 H₀,再使用同一份参考表继续分析:
0 / 39changed decisions recovered by file replacement只替换文件:被改变的决策恢复数
39 / 39changed decisions recovered by state restoration恢复执行状态:被改变的决策恢复数
The final decision is checked against the certified result. Under state restoration, all 102 requests submitted decisions that matched the reference: 39 changed decisions were recovered, and the other 63 remained unchanged.最终决策仍需与认证结果核对。在状态恢复条件下,102 个请求提交的决策全部与参考一致:39 个被改变的决策复原,其余 63 个保持不变。
05Check the final decision核对最终决策Check the final selection or testing assignment against the certificate and current inputs.核对最终名单或检测分配是否与认证结果一致,并确认它依据的是当前数据。
𝒰 contains the score vectors permitted by valid numerical evidence. acert is the single decision shared by all of them. a is the actual final decision.𝒰 包含有效数值证据允许的分数向量,acert 是这些向量共同给出的唯一决策。a 是实际最终决策。
Certification requires three checks: the score vectors permitted by valid evidence include the trusted reference; the rule gives the same decision throughout that set; and the submitted decision matches that result. If the agent has already used incorrect values, their effects on its history, variables and previously prepared decisions must also be addressed. Before recording the final decision, the system checks the certified result and the current input data again.认证需要确认三件事:有效证据允许的分数范围包含可信参考;规则对这个范围内的分数都给出同一决策;系统最终提交的决策与它一致。如果 Agent 已经使用过错误数值,还需要处理历史记录、变量和此前决策中保留的影响。记录最终决策前,系统会再次核对认证结果和当前输入数据。
In the hERG single-request experiment, every certificate came from full trusted recomputation.在 hERG 单请求实验中,每份证书均来自全量可信重算。
Extension: AdamW and all-reduce扩展阅读:AdamW 与 all-reduce
State and communication状态与通信
AdamW and all-reduce carry errors forwardAdamW 与 all-reduce 中的误差传播
Here, zₜ = (θₜ, mₜ, vₜ) denotes the components varied in the restoration experiments: parameters and AdamW moments. The remaining state, including counters, hyperparameters, random state and the sample stream, is matched across the compared continuations. Future computations depend on this state, not just the current predictions.这里 zₜ = (θₜ, mₜ, vₜ) 只表示恢复实验中改变的分量:参数与 AdamW 的一阶矩、二阶矩。其余状态,包括计数器、超参数、随机状态和样本流,在各条对比的后续计算中保持对应一致。未来计算依赖这些状态,而不只是当前预测。
In this section, t indexes optimizer updates. θt denotes model parameters, mt and vt the first- and second-moment accumulators, and 𝒯t the update map with the stated settings. 本节中的 t 是优化器更新步数。θt 是模型参数,mt、vt 分别是一阶矩和二阶矩累积量,𝒯t 是规定设置下的更新映射。
For an averaged all-reduce, captured local-gradient residuals contribute through their sum:对取平均的 all-reduce,捕获的局部梯度残差通过求和传播:
N counts the gradient contributions in the average and j indexes a contribution. γt,j is its gradient at update t, δt,j its captured candidate-minus-reference residual, and γ̄t the averaged gradient. Δγ̄t denotes the change in that average.N 是平均运算中的梯度贡献数量,j 是贡献索引。γt,j 是第 t 步对应的梯度,δt,j 是捕获的候选梯度减参考梯度的残差,γ̄t 是平均梯度,Δγ̄t 表示该平均值的变化。
The second relation describes the idealized pre-clipping residual contribution; reduction-rounding differences are checked separately. The experiments replay captured gradient differences before reduction.第二式描述裁剪前的理想化残差贡献,归约舍入差异另行核对。实验在归约前回放捕获的梯度差异。
Experimental results and data sources实验结果与数据来源
Experiment实验
Decision result决策结果
Other observations同时观察到的结果
Molecular ranking分子排序
One restored score recovers the full Top-10 order; reverse transplantation reproduces the changed order.恢复一个分数即可恢复完整 Top-10 顺序;反向移植重现改变后的顺序。
55 other scores still differ.仍有 55 个其他分数不同。
Compound-activity ranking化合物活性排序
Replacing two blocks recovers Top-20 membership in both confirmation captures.只替换两个块,两次确认捕获都恢复了 Top-20 成员。
After replacing two complete blocks, 98.32% and 98.52% of the differing activation entries remain.替换两个完整块后,仍有 98.32% 和 98.52% 的激活差异未被改动。
hERG testing assignmenthERG 检测分配
After R1, M additionally recomputes 68 of 2,009 compounds. Both rule outputs recover in all 16 fault sources.R1 之后,M 在 2,009 个化合物中追加重算 68 个。16 个故障来源的两种规则输出均恢复。
All 96 fresh Biomni trajectories on the repaired scores reproduce the healthy reference decisions.使用修复后分数新运行的 96 条 Biomni 轨迹,全部复现健康参考决策。
Distributed training分布式训练
In one continued-training run with eight processes across two nodes, all 1,017 predictions differ while Top-20 membership and order agree.在一次 8 进程、2 节点的继续训练中,全部 1,017 个预测不同,但 Top-20 成员与顺序一致。
All 63 stored FP32 losses also agree bit for bit.记录的 63 个 FP32 损失也逐位相同。
AdamW / distributed gradientsAdamW/分布式梯度
In delayed-restoration tests, all 16 complete-state configurations recover future endpoints and post-restoration logs.在延迟恢复实验中,16 个完整状态恢复配置全部恢复未来终点及恢复后的日志。
Partial restoration recovers membership in 30/32 configurations, while full order and numerical state still differ.部分恢复在 30/32 个配置中恢复了名单成员,完整排序与数值状态仍有差异。
Sources: paper and supplementary material, Appendices C (coordinate interventions and recovery cost), D (optimizer state and distributed gradients), and I (hERG recovery and commitment).依据:论文及补充材料,附录 C(坐标干预与恢复成本)、D(优化器状态与分布式梯度)、I(hERG 恢复与提交)。
02Method方法
Restore or transplant values at their original coordinates在原始坐标上恢复或移植数值
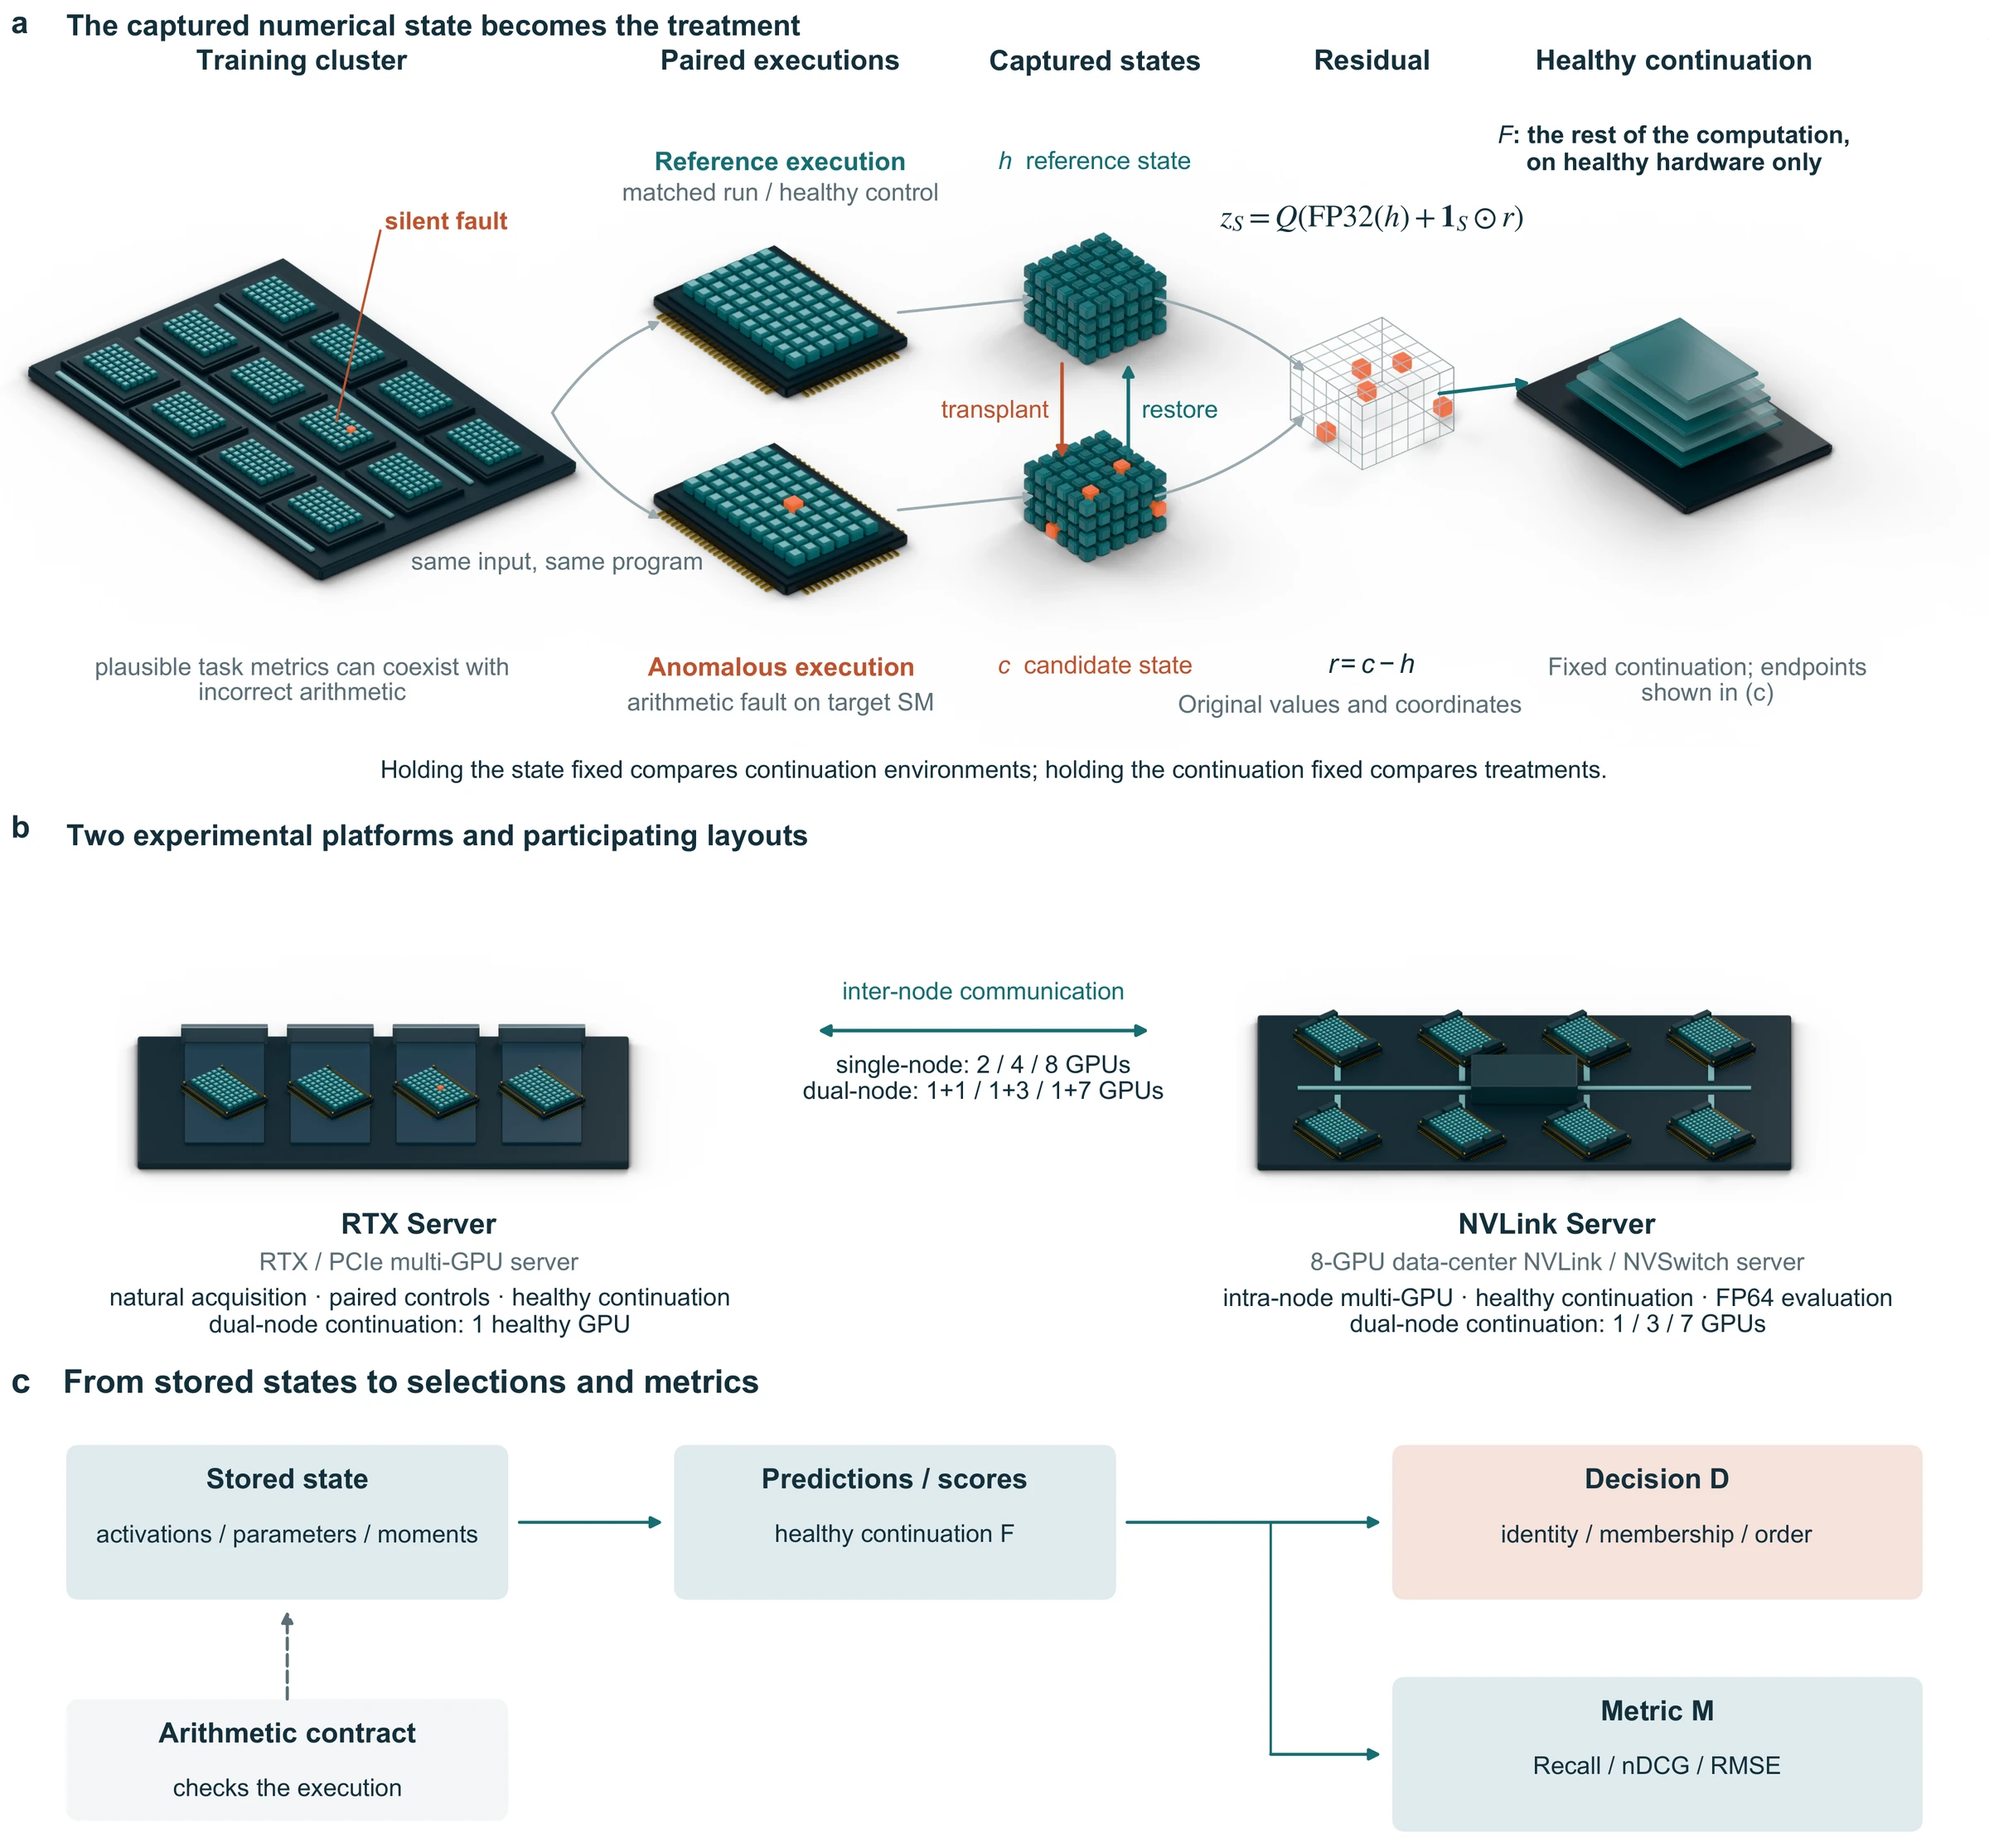
We study silent data corruption observed during distributed training. Erroneous outputs without NaN (not-a-number) or Inf (infinity) can pass ordinary monitoring and reach a tool result. Case 1 faults appear more often on tested large-matrix paths; Case 2 faults also appear on short probes.我们研究分布式训练中观察到的 GPU 静默数据损坏。未出现 NaN(非数值标记)或 Inf(无穷大)的错误输出,可能通过常规监测并进入工具结果。Case 1 在所测试的大矩阵路径上比短探针更常出现异常;Case 2 也在短探针中出现异常。
With inputs, model, representation and document order matched, BioAgent-DF saves a reference state h and a candidate state c at the same computation site. The remaining tool and agent steps run on healthy hardware, and repeated reference runs (H1, H2) measure the agent’s own variation.在输入、模型、数值表示与文档顺序匹配的条件下,BioAgent-DF 在同一计算位置保存参考状态 h 和候选状态 c。其余工具步骤与 Agent 推理在健康硬件上继续执行;重复参考运行 H1、H2 用于测量 Agent 自身的变化。
Enlarge放大Figure 3. Tool-state interventions and computing platforms. (a) Paired states supply original-coordinate restoration and transplantation on healthy hardware. (b) The PCIe and NVLink/NVSwitch layouts indicate computing roles and participation. (c) Arithmetic checks, stored states, selected objects and task metrics are recorded separately.图 3|工具状态干预与计算平台。(a)配对状态用于在原始坐标上进行恢复和移植,并在健康硬件上继续计算。(b)PCIe 与 NVLink/NVSwitch 布局说明不同设备的计算角色。(c)分别记录算术检查、保存状态、入选对象与任务指标。
03Mechanism机制
Selection turns small residuals into discrete changes排序竞争使细小残差改变入选对象
Tool outputs determine which items an agent can inspect, and selection is a competition. An unchanged score can still matter: for SciFact claim 684, one relevant document with an unchanged score leaves the top five after three competitors change, and restoring or transplanting any two competitor scores eliminates or reproduces the Recall@5 loss.工具输出决定 Agent 可以检查哪些对象,而选择取决于对象之间的竞争。对于 SciFact 声明 684,三个竞争文档的分数改变后,一个自身分数未变的相关文档退出前五名;恢复或移植任意两个竞争文档的分数,即可消除或重现 Recall@5 的下降。
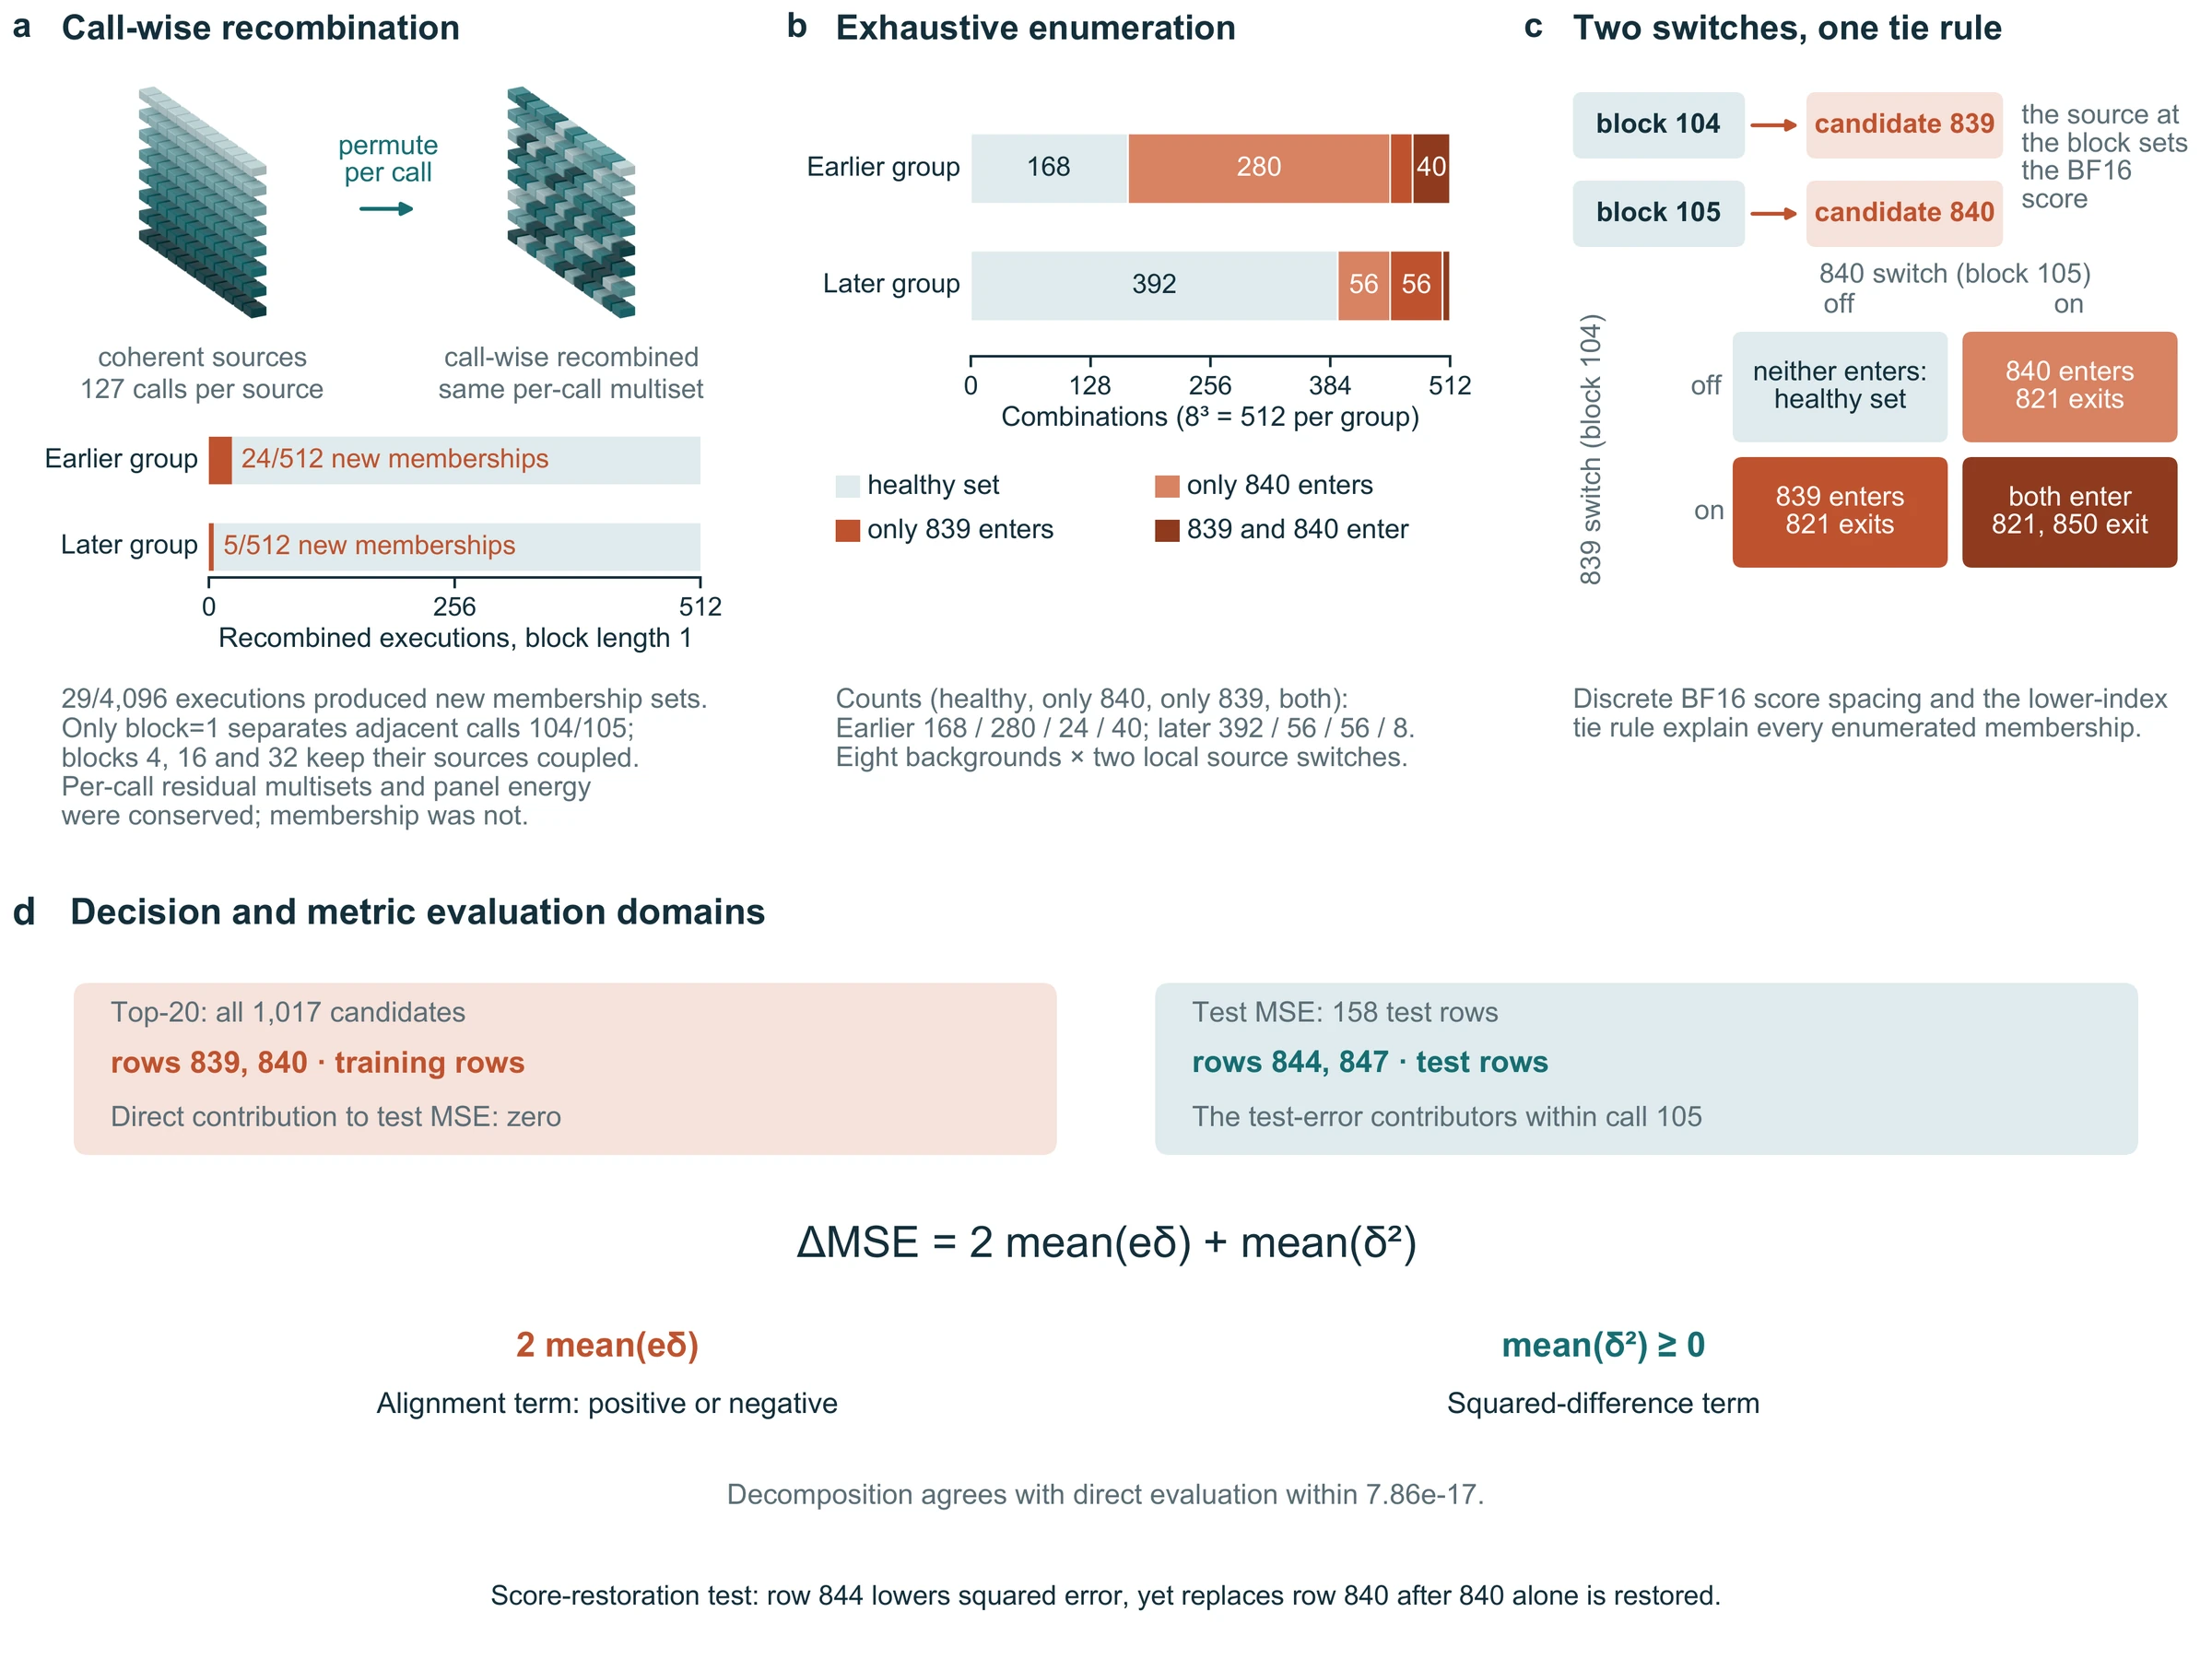
Recombining captured residuals across a panel of eight executions keeps each call’s values but changes which differences occur together. Of 4,096 recombined executions, 29 produce lists absent from their source group, and the BF16 score grid with a lower-index tie rule explains all 1,024 enumerated combinations.在八次计算之间重组捕获的残差,保留每次调用的数值,但改变哪些差异共同出现。4,096 次重组计算中,有 29 次产生了其来源组中未出现过的名单;BF16 分数间隔及较小索引优先的平局规则可以解释全部 1,024 个穷举组合。
Error decomposition误差分解
With reference error e and candidate-minus-reference difference δ on the same evaluation rows, when the two have opposite signs, MSE can fall even though the selection changes.在相同评价对象上,e 表示参考预测误差,δ 表示候选预测减参考预测;两者方向相反时,即使名单改变,均方误差 MSE 也可能降低。
Enlarge放大Figure 4. Recombination and competition. Finite combinations of captured residuals explain candidate membership and its relation to prediction error. The MSE panel shows the cross term and squared-difference term.图 4|残差重组与排序竞争。对捕获残差的有限组合进行分析,解释候选成员变化及其与预测误差的关系。MSE 面板给出交叉项与差异平方项。
04Metrics指标
Identical losses and metrics can hide changed states损失与指标相同,内部状态仍可能不同
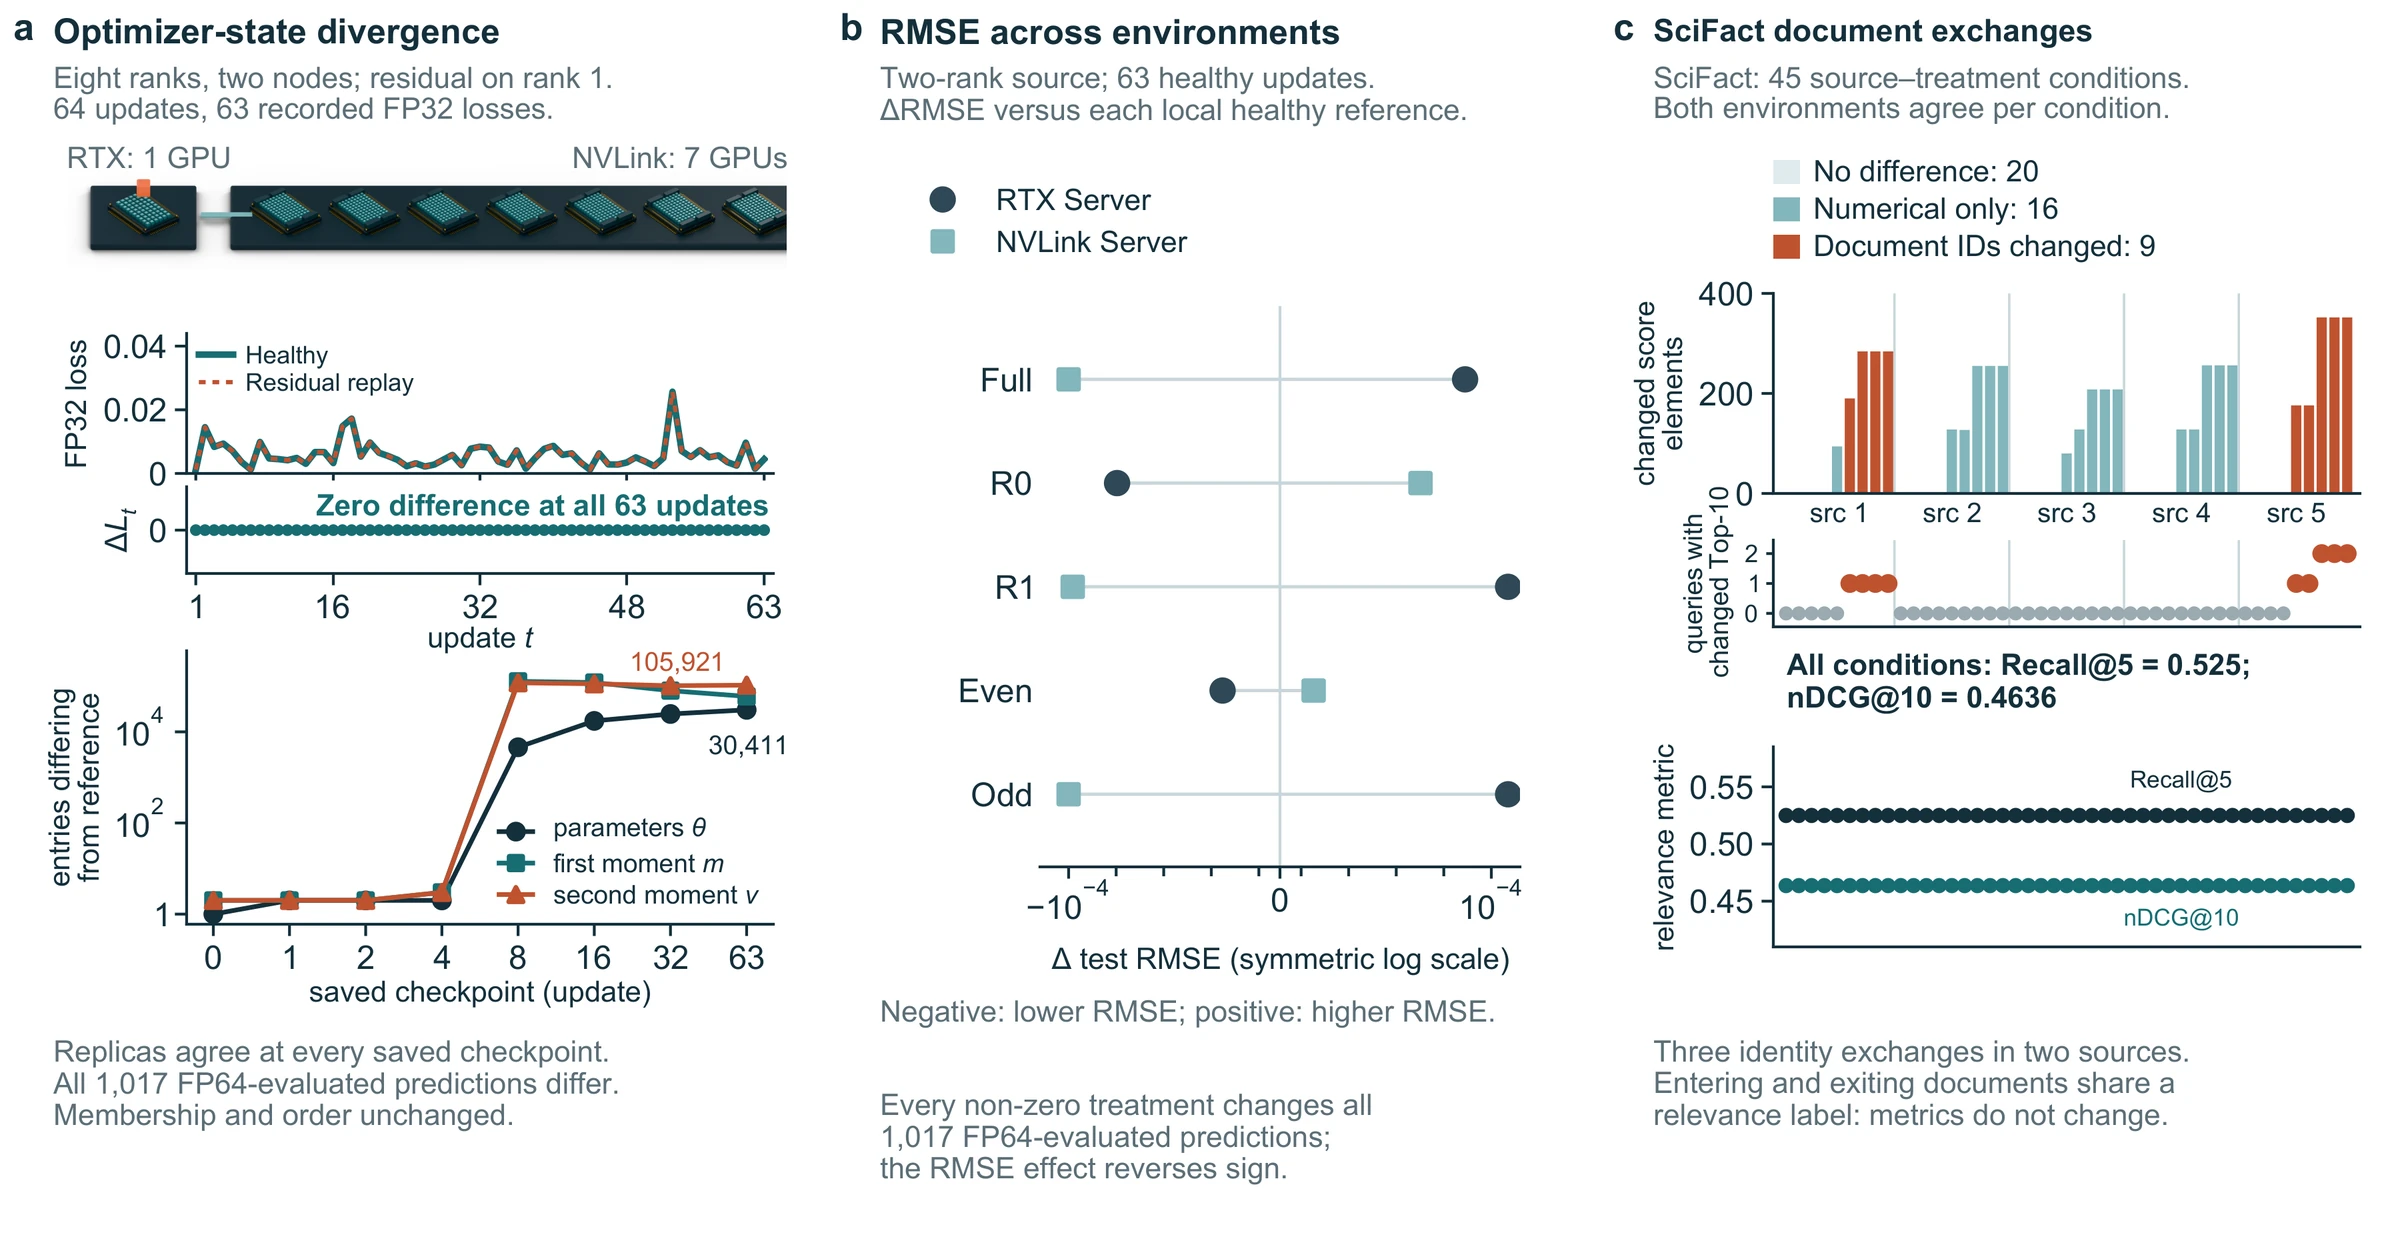
An eight-process, two-node training continuation records 63 bitwise-identical FP32 losses with synchronized replicas, yet 30,411 parameters, 60,025 first moments, 105,921 second moments and all 1,017 FP64 predictions differ from the reference.一次 8 进程、2 节点的继续训练,副本保持同步,记录的 63 个 FP32 损失逐位相同,但 30,411 个参数、60,025 个一阶矩和 105,921 个二阶矩条目以及全部 1,017 个 FP64 预测均与参考不同。
The direction of an effect can also depend on the healthy reference: the change in test RMSE reverses sign between RTX and NVLink environments. In SciFact, four of five new captures change which documents are retrieved while every query’s relevance-label sequence, Recall@5 and nDCG@10 stay the same.效应方向还可能取决于所用健康参考:测试集 RMSE 的变化在 RTX 与 NVLink 环境之间出现相反符号。SciFact 的五次新捕获中,有四次改变了检索文档,但每个查询的相关性标签序列、Recall@5 与 nDCG@10 都保持不变。
Enlarge放大Figure 5. Numerical and task endpoints. (a) State divergence with unchanged losses. (b) Reversal of RMSE direction across healthy environments. (c) Document changes with unchanged relevance labels.图 5|数值终点与任务终点。(a)损失不变时内部状态仍出现差异。(b)RMSE 的变化方向在健康环境之间反转。(c)检索到的文档改变,但相关性标签保持不变。
05SciFact claim 431SciFact 声明 431
Same verdict, different cited evidence结论不变,引用的证据变了
This mechanism study selected 27 Case 2 capture-claim combinations, covering 11 claims, because their upstream Top-10 retrieval lists had already changed.
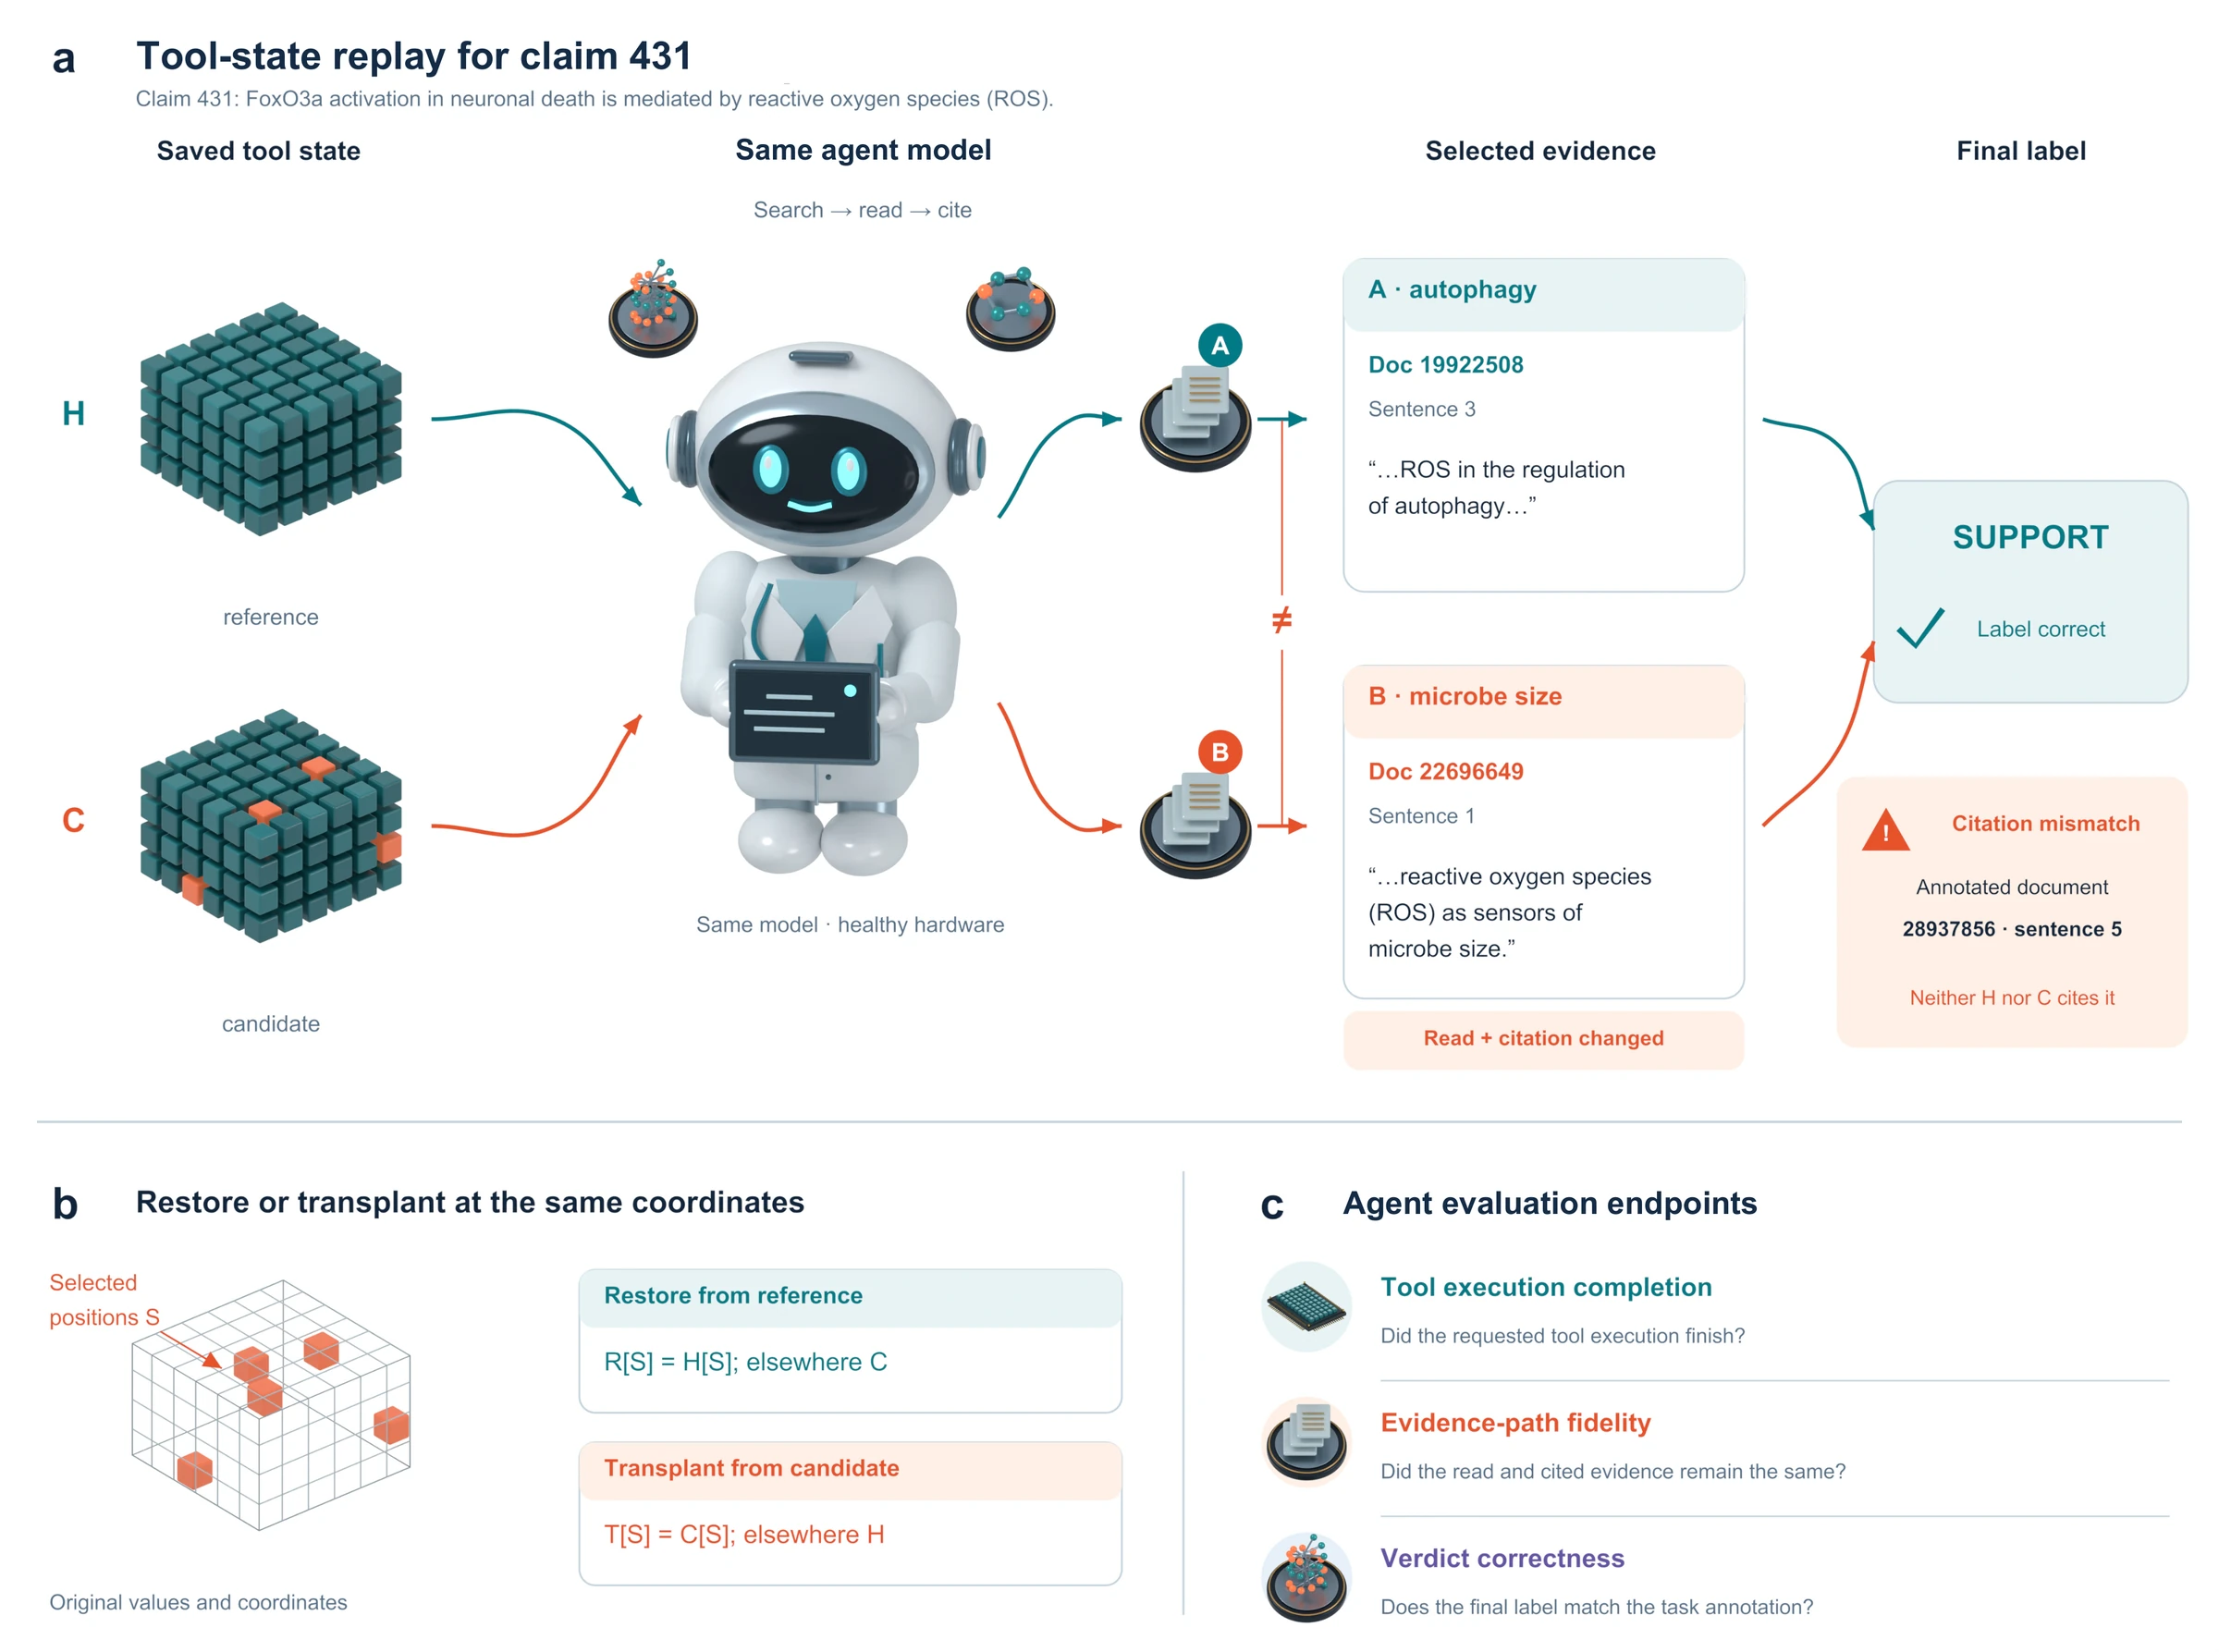
Claim 431 states that FoxO3a activation in neuronal death is mediated by reactive oxygen species. Replayed to the same Gemma 3 4B IT model on healthy hardware, the reference state leads the agent to cite a sentence about ROS and autophagy (19922508/3), and the candidate state a sentence on ROS sensing microbe size (22696649/1). Neither sentence supports the stated FoxO3a mechanism and neither matches the annotated evidence (28937856/5), yet both branches return the SUPPORT label that matches the benchmark annotation.
All 27 selected combinations were rerun in eight further batches with the request seed fixed. Three Qwen3.5-4B combinations show the same citation change in every batch; four Gemma 3 4B IT combinations show the same read and citation change. H1, H2 and full restoration agree, and verdicts do not change. These seven combinations involve only claims 431 and 729.
机制实验选取了 27 个 Case 2 捕获与声明的组合,覆盖 11 条声明,筛选依据是上游 Top-10 检索列表已经发生变化。
声明 431 讨论神经元死亡中由活性氧介导的 FoxO3a 激活。在健康硬件上回放给同一 Gemma 3 4B IT 模型时,参考状态让 Agent 引用关于活性氧与自噬的句子(19922508/3),候选状态让它引用关于活性氧感知微生物大小的句子(22696649/1)。两句话都不支持声明中的 FoxO3a 机制,也都不是标注证据(28937856/5),但两条轨迹均给出与基准标注一致的 SUPPORT 标签。
In a separate, unselected set of Qwen runs, 382 of 421 groups completed every condition with the agent reading the tool result; the other 39 were incomplete or the agent did not read the result. Disagreements between candidate and reference runs were no greater than disagreements between healthy repeats (paper Table 2).在另一组未经筛选的 Qwen 运行中,421 组里有 382 组各条件均完成,且 Agent 读取了工具结果,其余 39 组未完成或未读取结果。候选状态相对参考状态的差异不高于健康重复之间的差异(论文表 2)。
Groups that differ, among the same 382 groups同一批 382 个完成且已读取结果的组中,发生差异的组数
Endpoint比较项
C vs H1C 与 H1
H2 vs H1H2 与 H1
Documents read读取的文档
3/382
4/382
Cited sentences引用句子
5/382
8/382
Verdict结论标签
2/382
2/382
C is the candidate state; H1 and H2 repeat the healthy reference state. All confidence intervals for the excess disagreement rate relative to healthy repeats include zero. Separate unselected controls for claims 350 and 1180 also showed no read, citation or verdict changes in their completed comparison subsets; baseline Gemma completed only claim 350.C 为候选状态,H1 与 H2 为健康参考状态的重复运行。候选与参考的差异率减去健康重复差异率,所得差值的置信区间均包含零。另行设置的未筛选声明 350 与 1180 对照,在已完成的比较子集中也未出现读取、引用或结论变化;基线 Gemma 完成的子集仅覆盖声明 350。
Record the evidence and experimental choices behind a result, and compare their changes with healthy-repeat variation.记录结果背后的证据与实验选择,并将其变化与健康重复的波动比较。
Enlarge放大Figure 6. The same verdict from different cited evidence. (a) Reference and candidate tool states are supplied to the same agent model on healthy hardware. Claim 431 concerns ROS-mediated FoxO3a activation in neuronal death. Gemma’s reference branch cites a sentence about ROS and autophagy (19922508/3), and its candidate branch cites ROS sensing microbe size (22696649/1). Neither sentence supports the stated FoxO3a mechanism, yet both branches return the SUPPORT label that matches the benchmark annotation. Neither citation matches the annotated evidence, 28937856/5. Sentence indices are zero-based and document identifiers are SciFact IDs. (b) Restoration and transplantation select values at their original coordinates. (c) Tool execution completion, evidence-path fidelity, and verdict correctness are evaluated. H1 and H2 repeat the same reference state.图 6|结论相同,引用证据不同。(a)参考与候选工具状态提供给健康硬件上的同一 Agent。声明 431 涉及神经元死亡中活性氧介导的 FoxO3a 激活。Gemma 的参考轨迹引用活性氧与自噬的句子(19922508/3),候选轨迹引用活性氧感知微生物大小的句子(22696649/1)。两句话均不支持该 FoxO3a 机制,也不匹配标注证据 28937856/5,但两条轨迹均返回与基准标注一致的 SUPPORT 标签。句子索引从零开始,文档编号为 SciFact ID。(b)恢复与移植选取原始坐标上的数值。(c)分别评价工具执行完成、证据路径保真与结论正确性。H1、H2 重复使用同一参考状态。
Citation引用
BibTeX
@misc{yi2026toolstate,
  title         = {From Tool State to Scientific Action: Auditing Decision
                   Provenance in Biomedical Research Agents},
  author        = {Yi, Xingyu and Zhang, Xinya and Zhou, Yunshen and Bao, Haoyu},
  year          = {2026},
  eprint        = {2611.01527},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://arxiv.org/abs/2611.01527}
}